mirror of
https://github.com/domainaware/parsedmarc.git
synced 2026-11-11 03:11:33 +00:00

 Sean WhalenandClaude Fable 5.2
d9193eafea
* Reject reports whose index-naming date is more than two days in the future (#947)

The date that names a report's dated Elasticsearch/OpenSearch index (an
aggregate report's begin date, a failure report's Arrival-Date, an SMTP
TLS report's start-datetime) was never compared with the present, so a
report dated 2100 named an index for 2100. Each parser now rejects such a
report with its own Invalid*Report; past dates stay unbounded.

Co-Authored-By: Claude Sonnet 5.5 <noreply@anthropic.com>

* Refuse an input larger than the report size cap before parse_report_file() reads it (#949)

The 32 MiB cap was applied only after the whole input was read. A path is
now checked with os.path.getsize(), bytes-like input with len(), and a
file object is read at most one byte past the cap. The error is the
ParserError with the message the content check already gives. Three
existing tests that fed over-cap content now see the earlier rejection.

Co-Authored-By: Claude Sonnet 5.5 <noreply@anthropic.com>

* Measure a memoryview input by its byte size

len() of a memoryview counts items, which are not bytes for every format,
so the size cap in parse_report_file() compares nbytes instead.

Co-Authored-By: Claude Fable 5.2 <noreply@anthropic.com>

* Bound the aggregate end date and read file objects to their end

Address the Copilot review of #954. A normalized report's per-day records
name their indexes from their own interval starts, so the report's end date
is bounded like its begin date. A raw stream may return fewer bytes than
asked for before its end, so parse_report_file() now reads in a loop until
end of file or one byte past the cap.

Co-Authored-By: Claude Fable 5.2 <noreply@anthropic.com>

* Accumulate bounded reads in one buffer

Address the second Copilot review of #954. Keeping every chunk in a list
cost one bytes object per read, about 85 bytes per byte for a stream that
returns a byte at a time (22.7 MiB for 256 KiB of input). One bytearray
keeps memory proportional to the bytes read.

Co-Authored-By: Claude Fable 5.2 <noreply@anthropic.com>

---------

Co-authored-by: Claude Sonnet 5.5 <noreply@anthropic.com>
parsedmarc


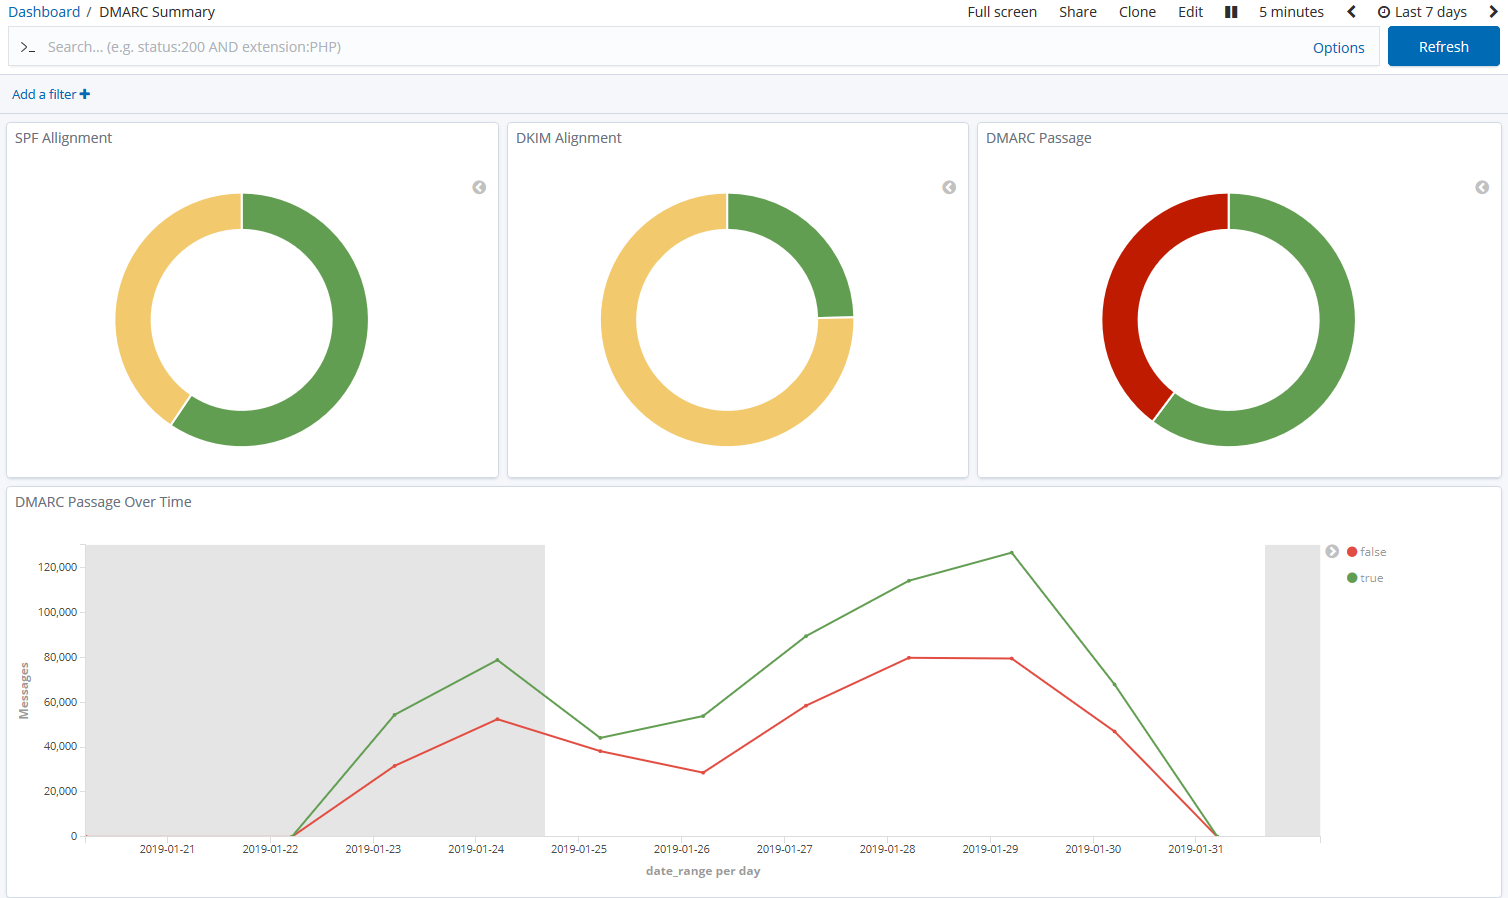
parsedmarc is a Python module and CLI utility for parsing DMARC
reports. When used with Elasticsearch and Kibana (or Splunk), or with
OpenSearch and Grafana, it works as a self-hosted open-source
alternative to commercial DMARC report processing services such as
Agari Brand Protection, Dmarcian, OnDMARC, ProofPoint Email Fraud
Defense, and Valimail.
Note
Domain-based Message Authentication, Reporting, and Conformance (DMARC) is an email authentication protocol.
Sponsors
This project is maintained by one developer. Please consider sponsoring my work if you or your organization benefit from it.
Features
- Parses aggregate/rua DMARC reports: the legacy draft and 1.0 schemas (RFC 7489) and the new RFC 9990 schema for the final DMARC standard (RFC 9989)
- Parses failure/ruf DMARC reports (RFC 6591 and RFC 9991; formerly called forensic reports)
- Parses reports from SMTP TLS Reporting (TLS-RPT, RFC 8460)
- Can parse reports from an inbox over IMAP, Microsoft Graph, or Gmail API
- Transparently handles gzip or zip compressed reports
- Consistent data structures
- Simple JSON and/or CSV output
- Optionally email the results
- Optionally send the results to Elasticsearch, OpenSearch, Splunk, or PostgreSQL, for use with premade dashboards
- Optionally send the results to Apache Kafka, Amazon S3, Azure Log Analytics (Microsoft Sentinel), a Graylog (GELF) endpoint, a syslog server, Grafana Loki, or an HTTP webhook
Python Compatibility
This project supports the following Python versions, which are either actively maintained or are the default versions for RHEL or Debian.
| Version | Supported | Reason |
|---|---|---|
| < 3.6 | ❌ | End of Life (EOL) |
| 3.6 | ❌ | Used in RHEL 8, but not supported by project dependencies |
| 3.7 | ❌ | End of Life (EOL) |
| 3.8 | ❌ | End of Life (EOL) |
| 3.9 | ❌ | Used in Debian 11 and RHEL 9, but not supported by project dependencies |
| 3.10 | ❌ | End of Life (EOL) |
| 3.11 | ✅ | Actively maintained; supported until June 2028 (Debian 12) |
| 3.12 | ✅ | Actively maintained; supported until May 2035 (RHEL 10) |
| 3.13 | ✅ | Actively maintained; supported until June 2030 (Debian 13) |
| 3.14 | ✅ | Supported (requires imapclient>=3.1.0) |
| 3.15 | ✅ | Supported |